We run our own systems this way
ShiftTracker is ours, in production, with real users. The monitoring and on-call practice we sell is the one we depend on ourselves.
Monitoring, on-call, patching and the ongoing changes that keep software useful — for systems we built and for systems we inherited. We operate our own platforms in production, so this is the same discipline we apply to ourselves.
Or see how we engage first — four shapes, no sales call required.
No more outages your customers report before you notice
Forget dependencies three major versions out of date
Stop relying on one person who knows how it works
Skip the backup nobody has ever restored from
Done with the same incident happening a fourth time
Say bye to a supplier who stopped answering the phone
24/7
cover available, with a named escalation pathBackendz
2
platforms we run ourselves, under the same disciplineBackendz
Every
incident gets a written review and a fix, not a restartour rule
ShiftTracker is ours, in production, with real users. The monitoring and on-call practice we sell is the one we depend on ourselves.
Every incident gets a written review and a change that stops it recurring. Restarting the service is a mitigation, not a resolution.
Inherited systems with no documentation and an absent author are normal work for us. We start with an audit and tell you what we find, including the bad news.
Runbooks, access and documentation stay current and stay yours. If you bring it in-house, you get a working handover rather than a dependency.
Most enquiries land in one of these. If yours does not, say so on the call — we would rather shape the engagement than sell you the nearest shape we have.
Monitoring, alerting and a response commitment on a system that currently has none.
Best for: Production systems where nobody is formally on call.
Patching, dependency upgrades and the small changes that stop a codebase becoming unmaintainable.
Best for: Stable systems that must not quietly rot.
A system that runs the business, built by someone who has gone. We take it on deliberately rather than discovering it during an incident.
Best for: Departed developers, acquired systems, dormant suppliers.
A standing capacity for the changes the business keeps asking for, on top of keeping the lights on.
Best for: Live systems with a steady stream of requests.
Every card is a build we shipped and still support. Open one for the decisions behind it.
What falls inside this service. Nothing here is an upsell discovered later.
The sequence matters more than the label. Skipping the first one is how projects in this area go wrong.
Code, infrastructure, access, backups and dependencies, with a written risk register. We would rather find the problems now than during an incident.
Operations directors, CTOs and plant managers — the ones still using the system a year after the invoice cleared.
 Freight operator · 14 depotsFreight operator · 14 depots
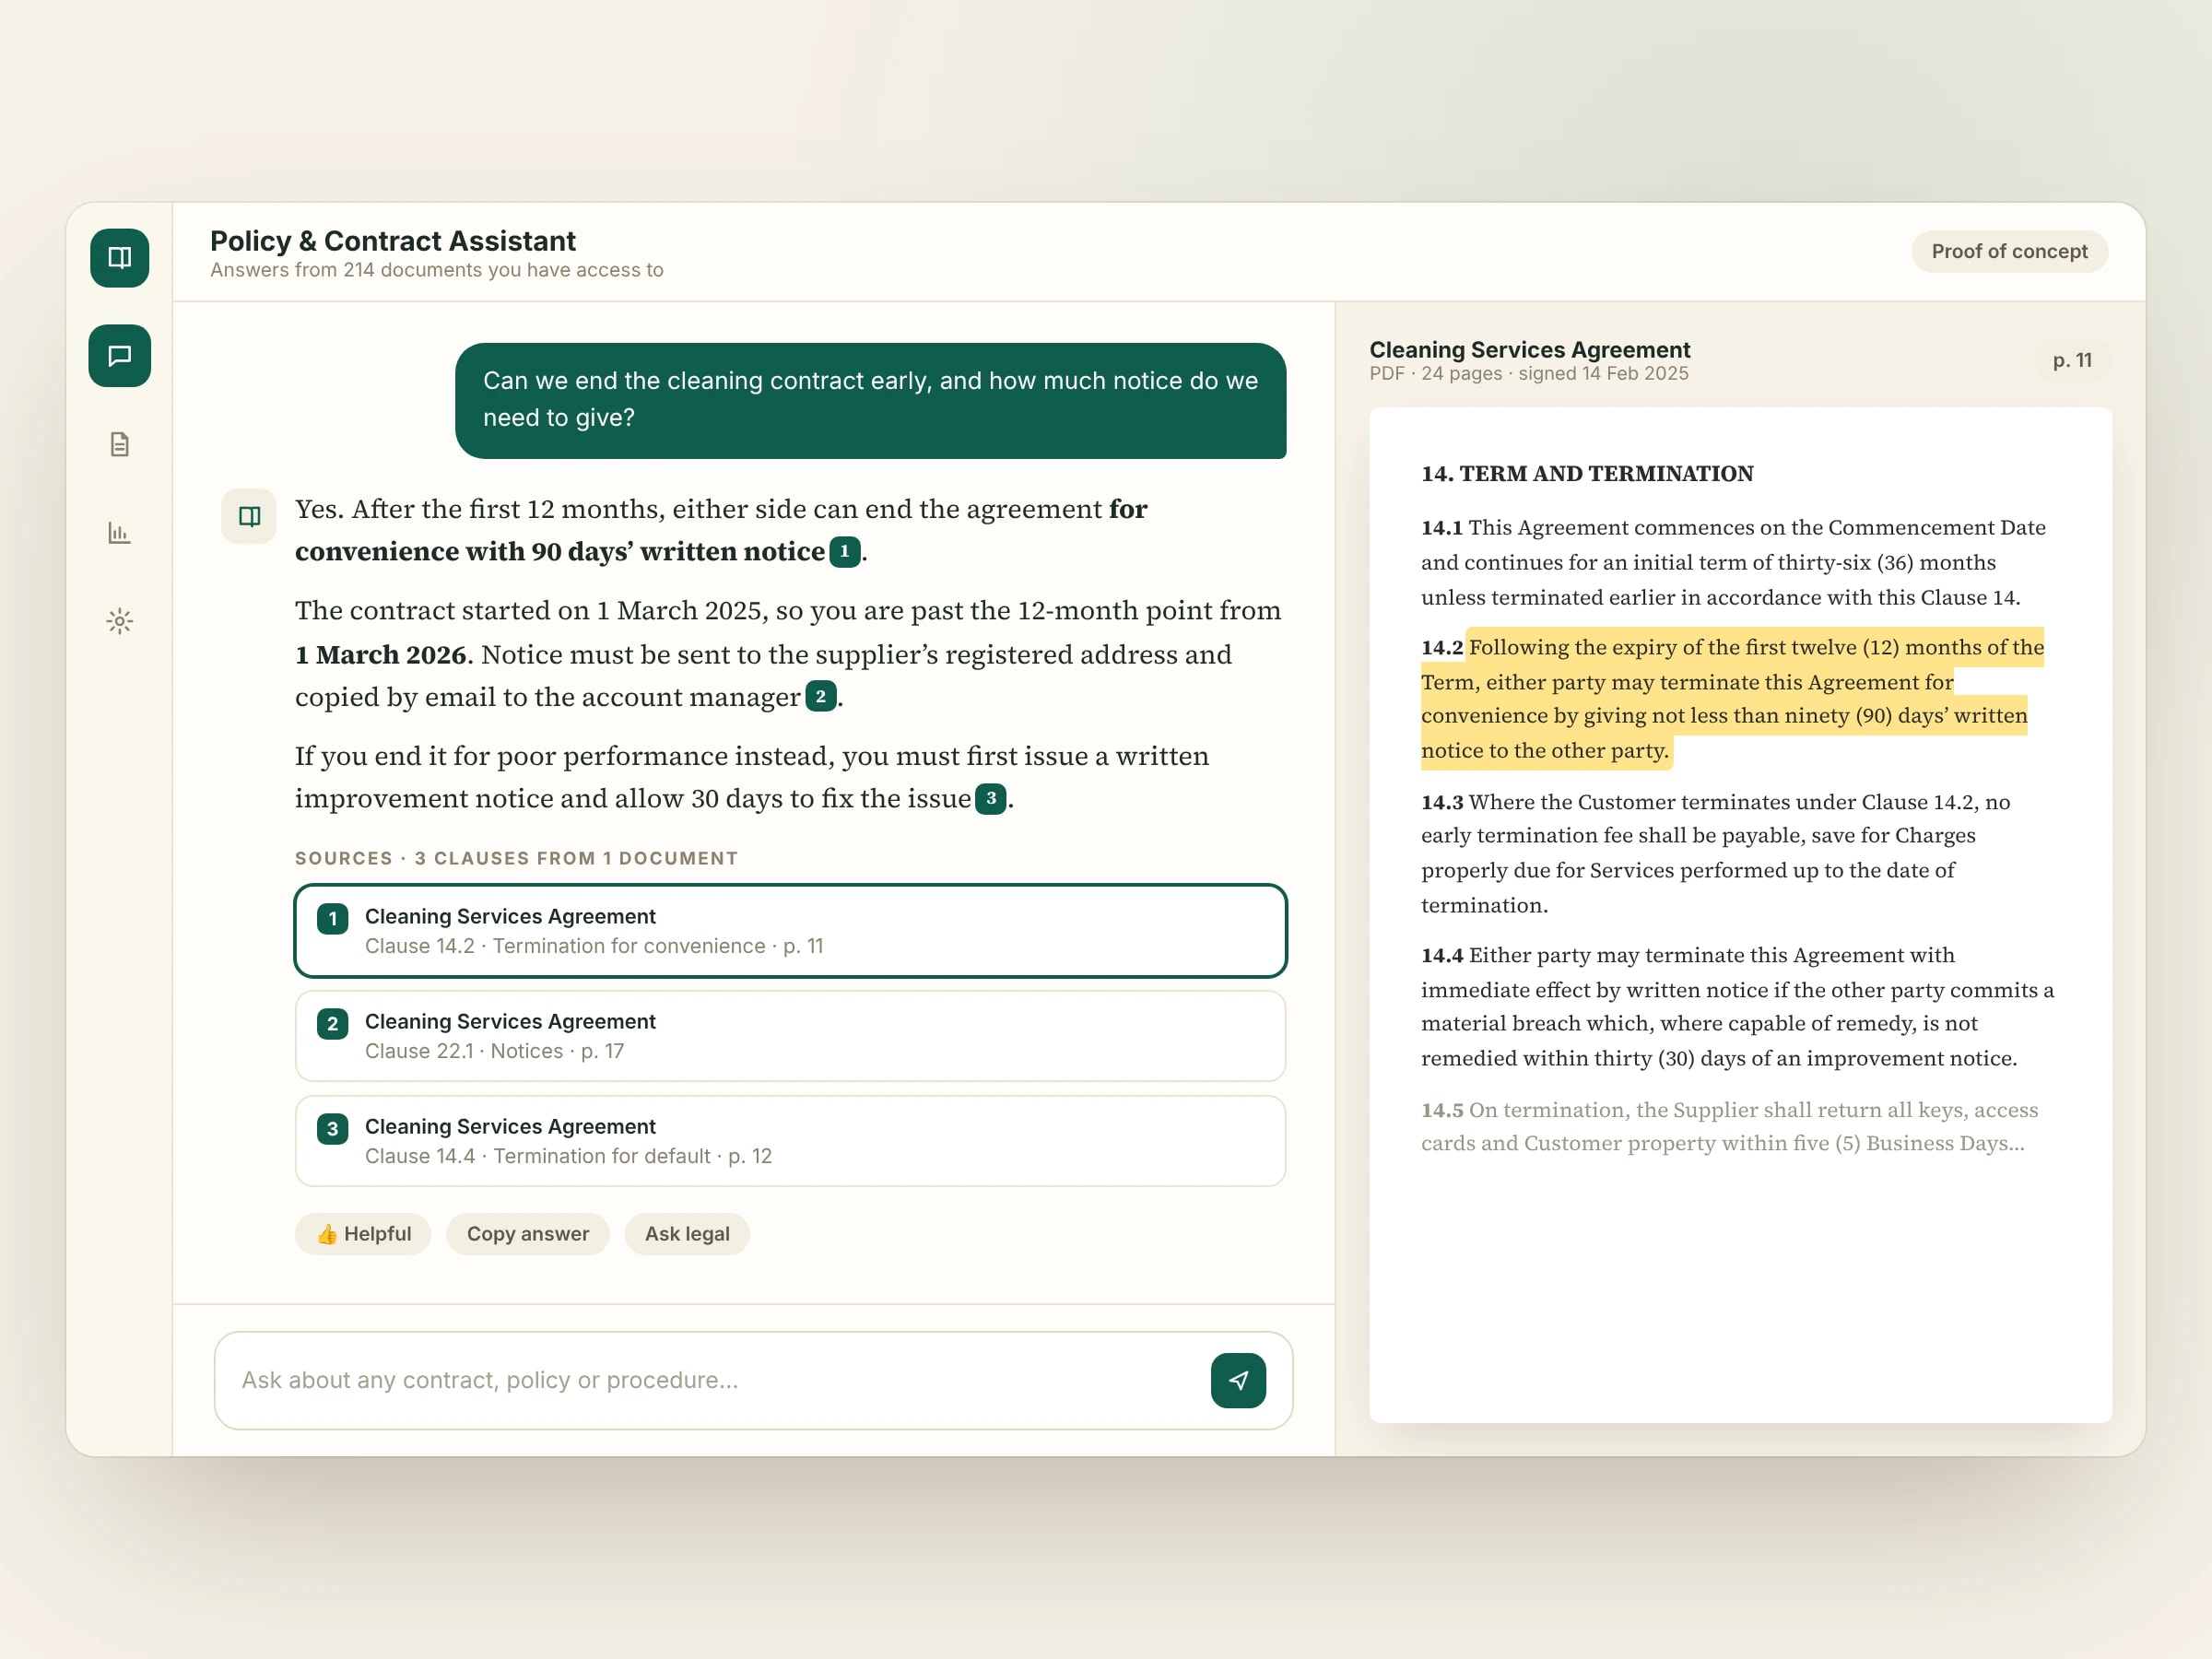
We wanted answers our team could check against the original document. Having the relevant clause beside the response makes the assistant useful when reviewing policies and contracts.
Our rental journey had to work for both vehicle owners and travellers. Backendz brought listings, availability and bookings together into a platform that feels straightforward to use.
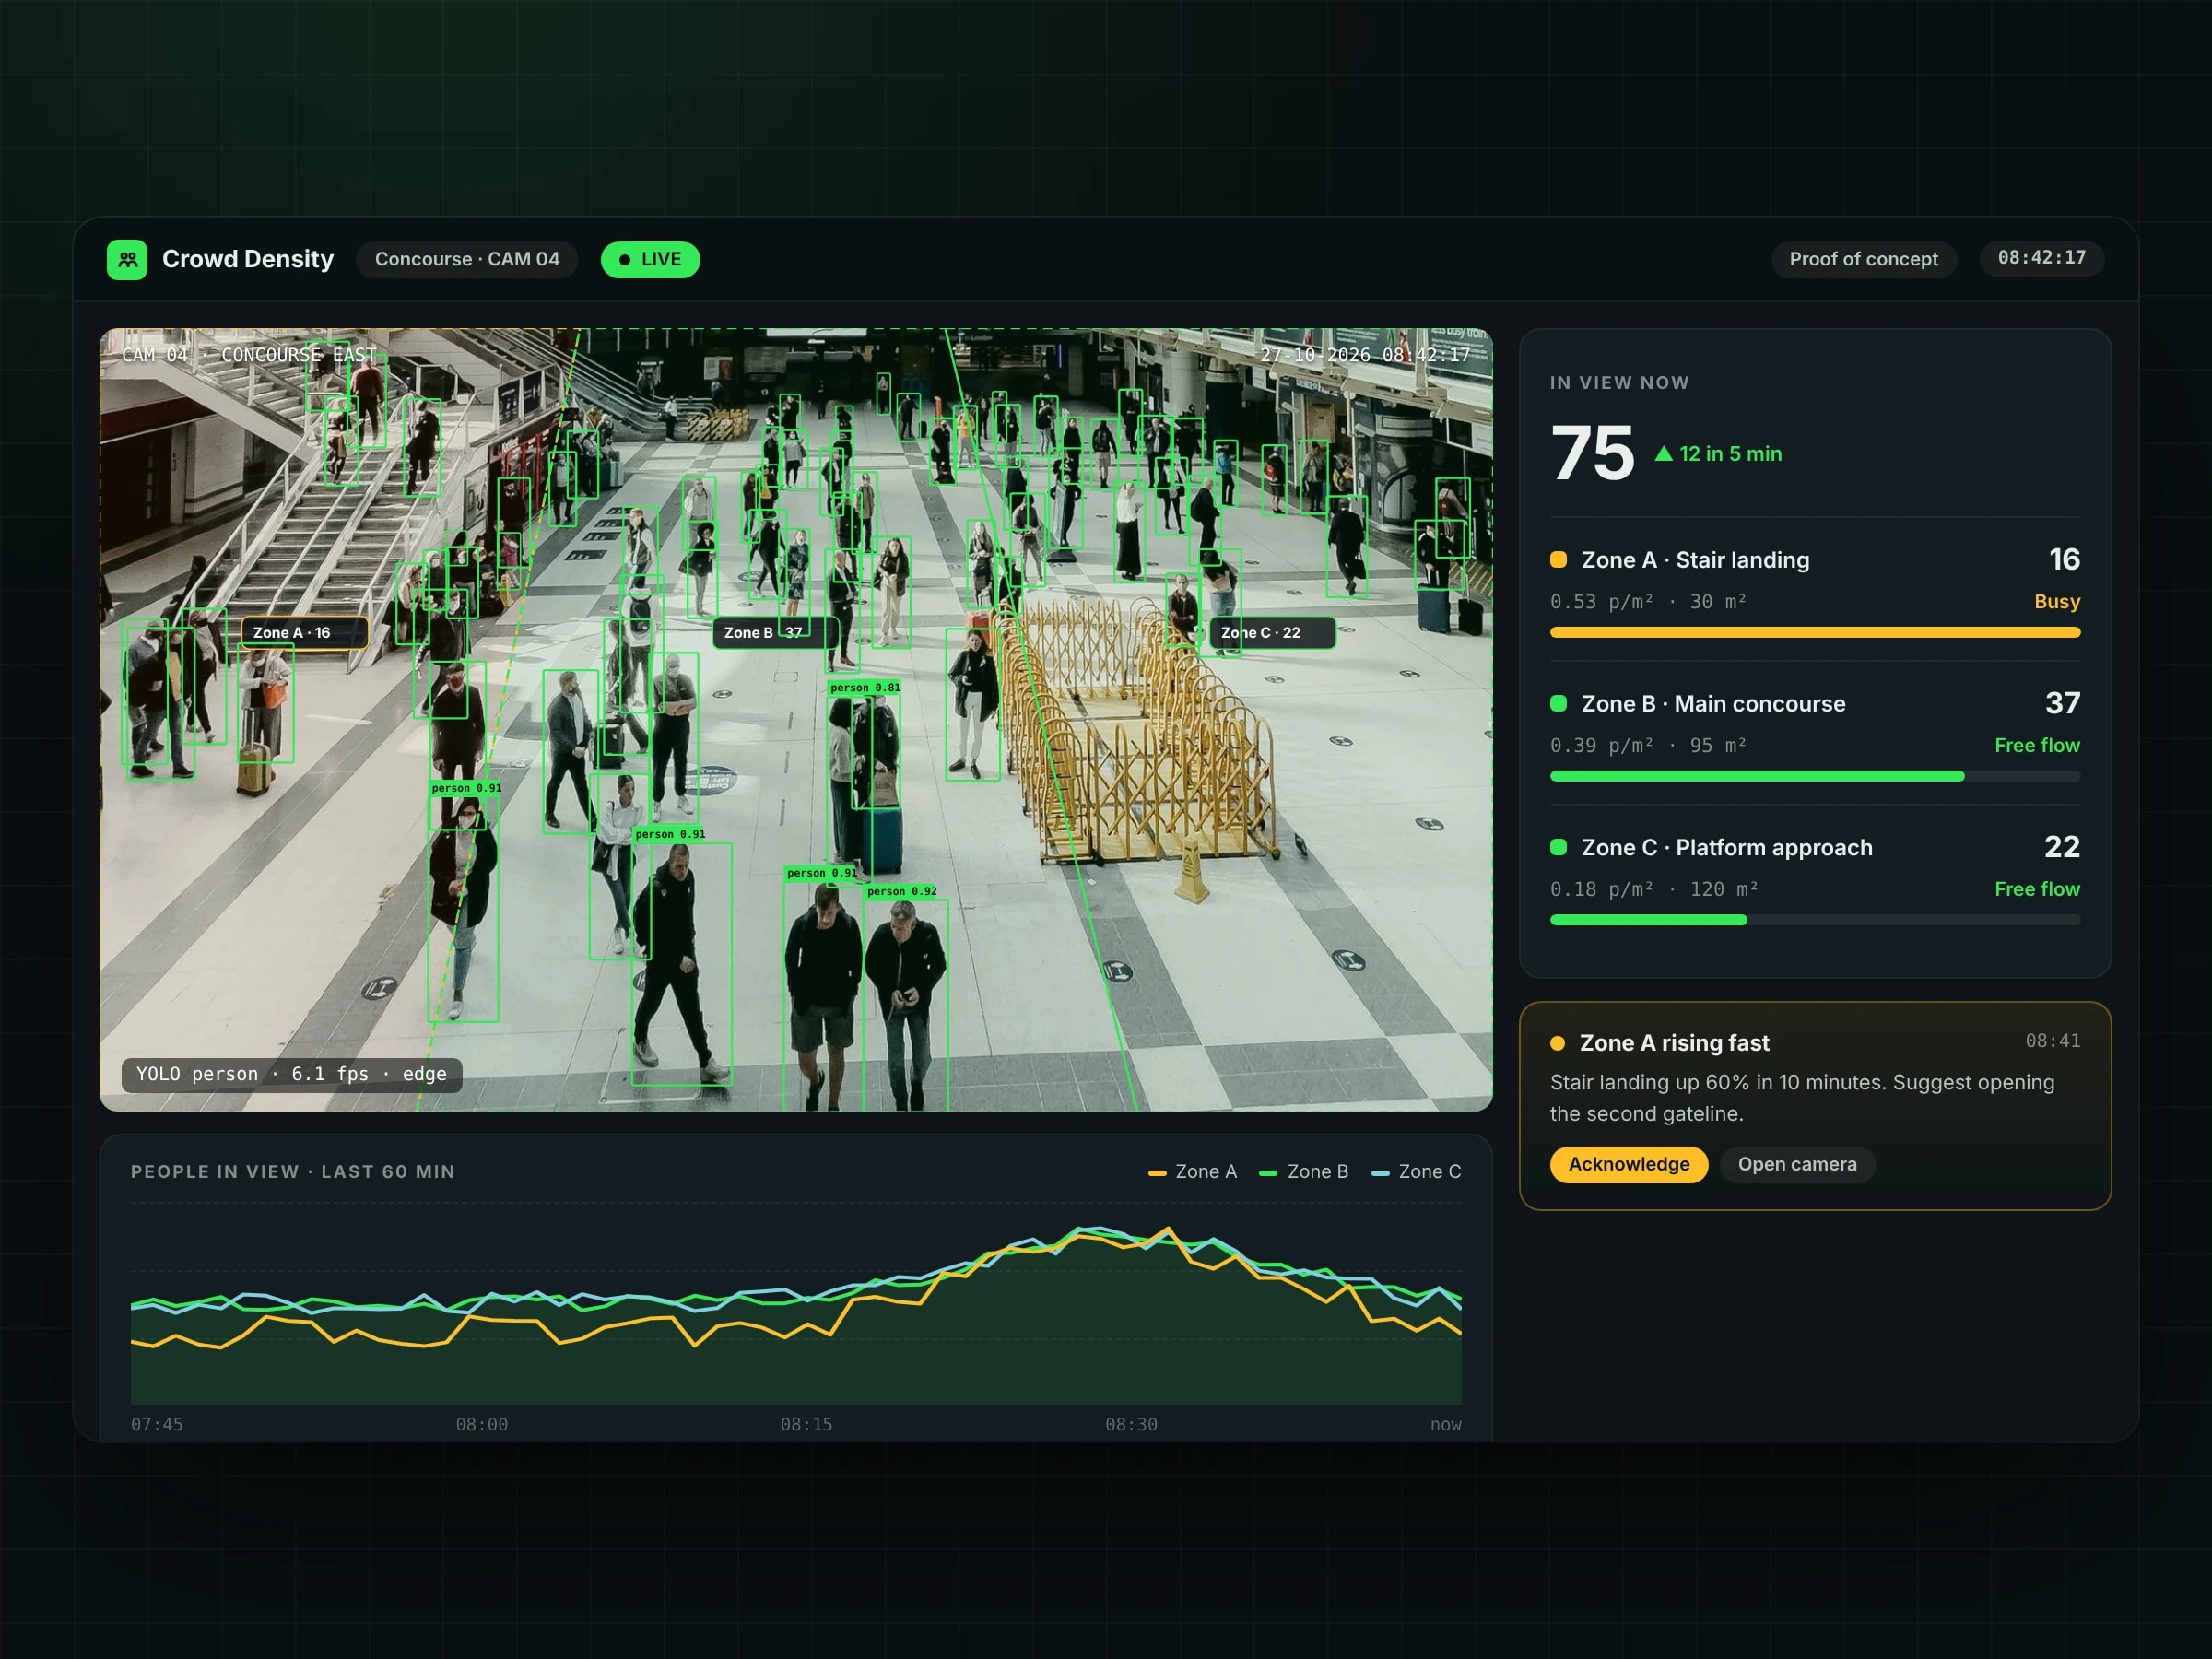
A single headcount does not tell us where congestion is developing. The zone-based view gives our team a clearer picture of how people are moving and where attention may be needed.
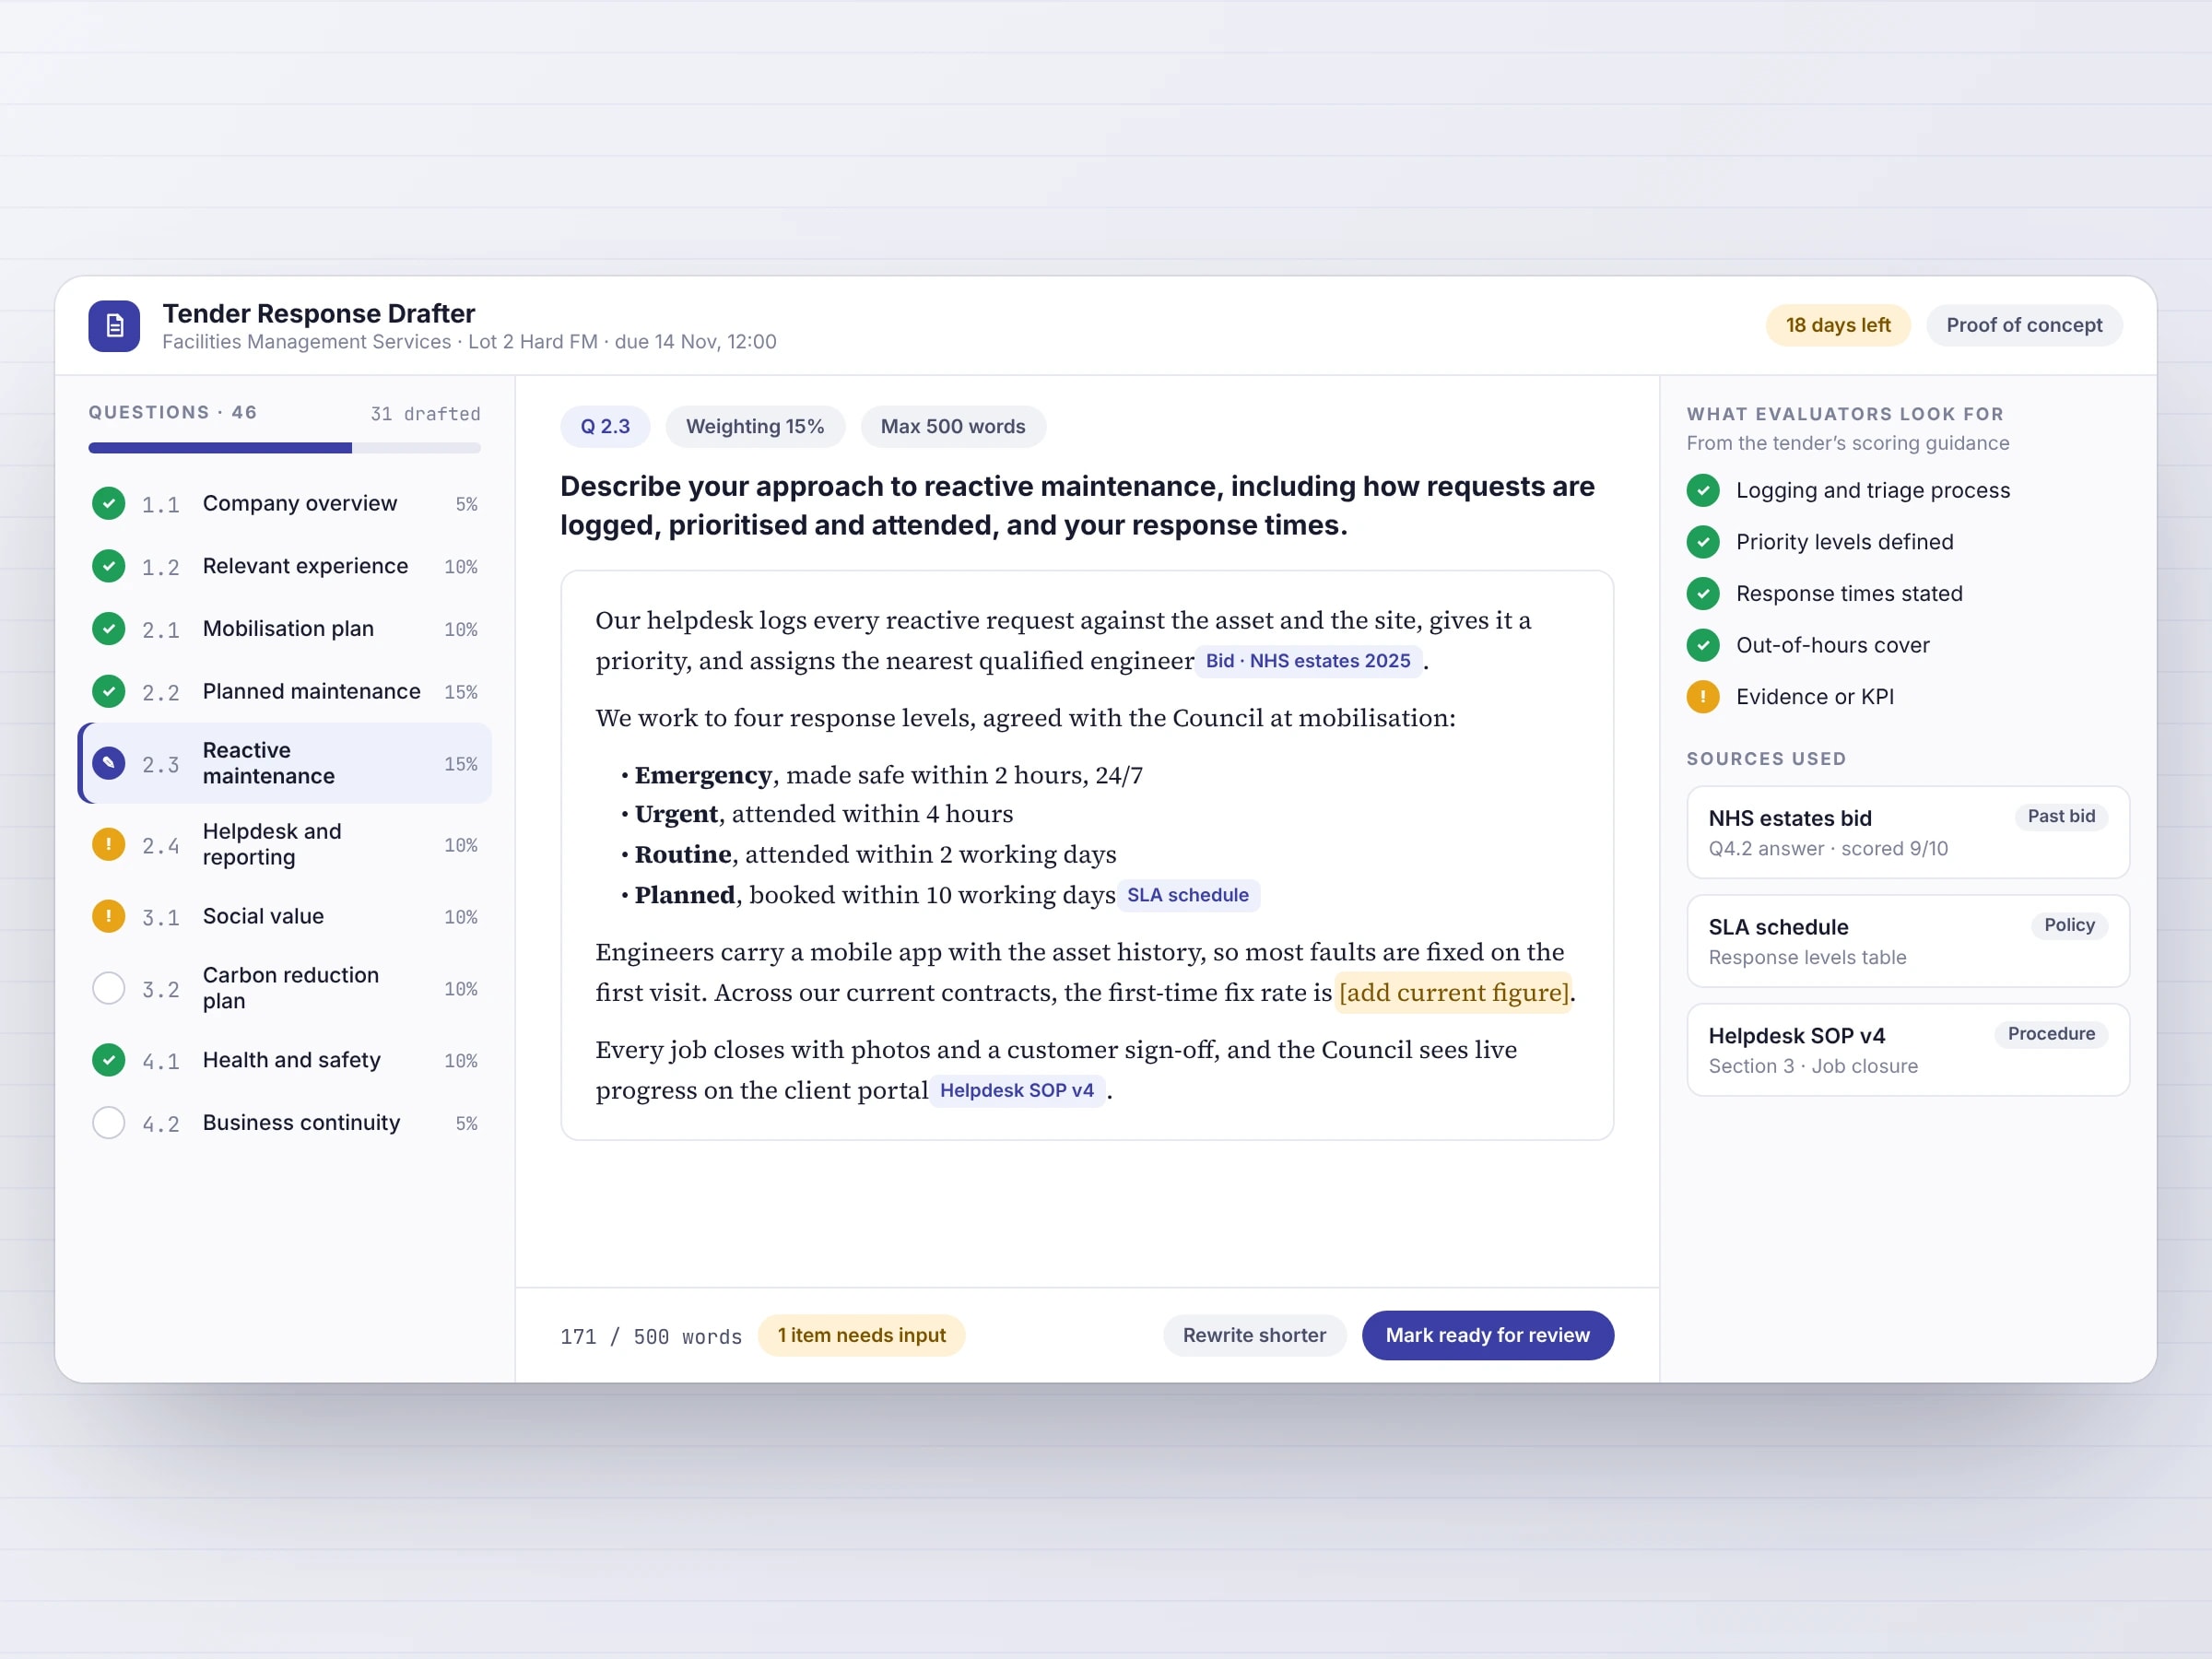
Tender preparation involves gathering evidence and getting the right people to review each section. Backendz brought those steps into one workspace, with drafts our team can check and approve.
Our estimating process needed to reflect how we actually price work. Backendz took time to understand the inputs and rules, then built a quoting journey our team could review and refine.
The team took time to understand how our staff work between appointments. The resulting system brings scheduling and client information together without making the day more complicated.
We could review working features throughout the build and give specific feedback. That made it easier to keep the product focused on the people using it.
Our field team needed access to job details away from the office. The mobile workflow keeps the relevant information close at hand and gives the office a clearer view of progress.
We wanted a client portal that reflected how we deliver our services. Backendz brought documents, requests and progress updates into a straightforward experience for clients and staff.
Our teams were entering the same information into several tools. Backendz mapped the process with us and built a more connected workflow with clear review points.
We needed scheduling, availability and shift changes in one place. Backendz shaped the system around the way our operations team works and stayed involved after launch to help us refine it.
Ask for references and we will put you on a call with the team that runs the system — not a case study PDF.
References available on request
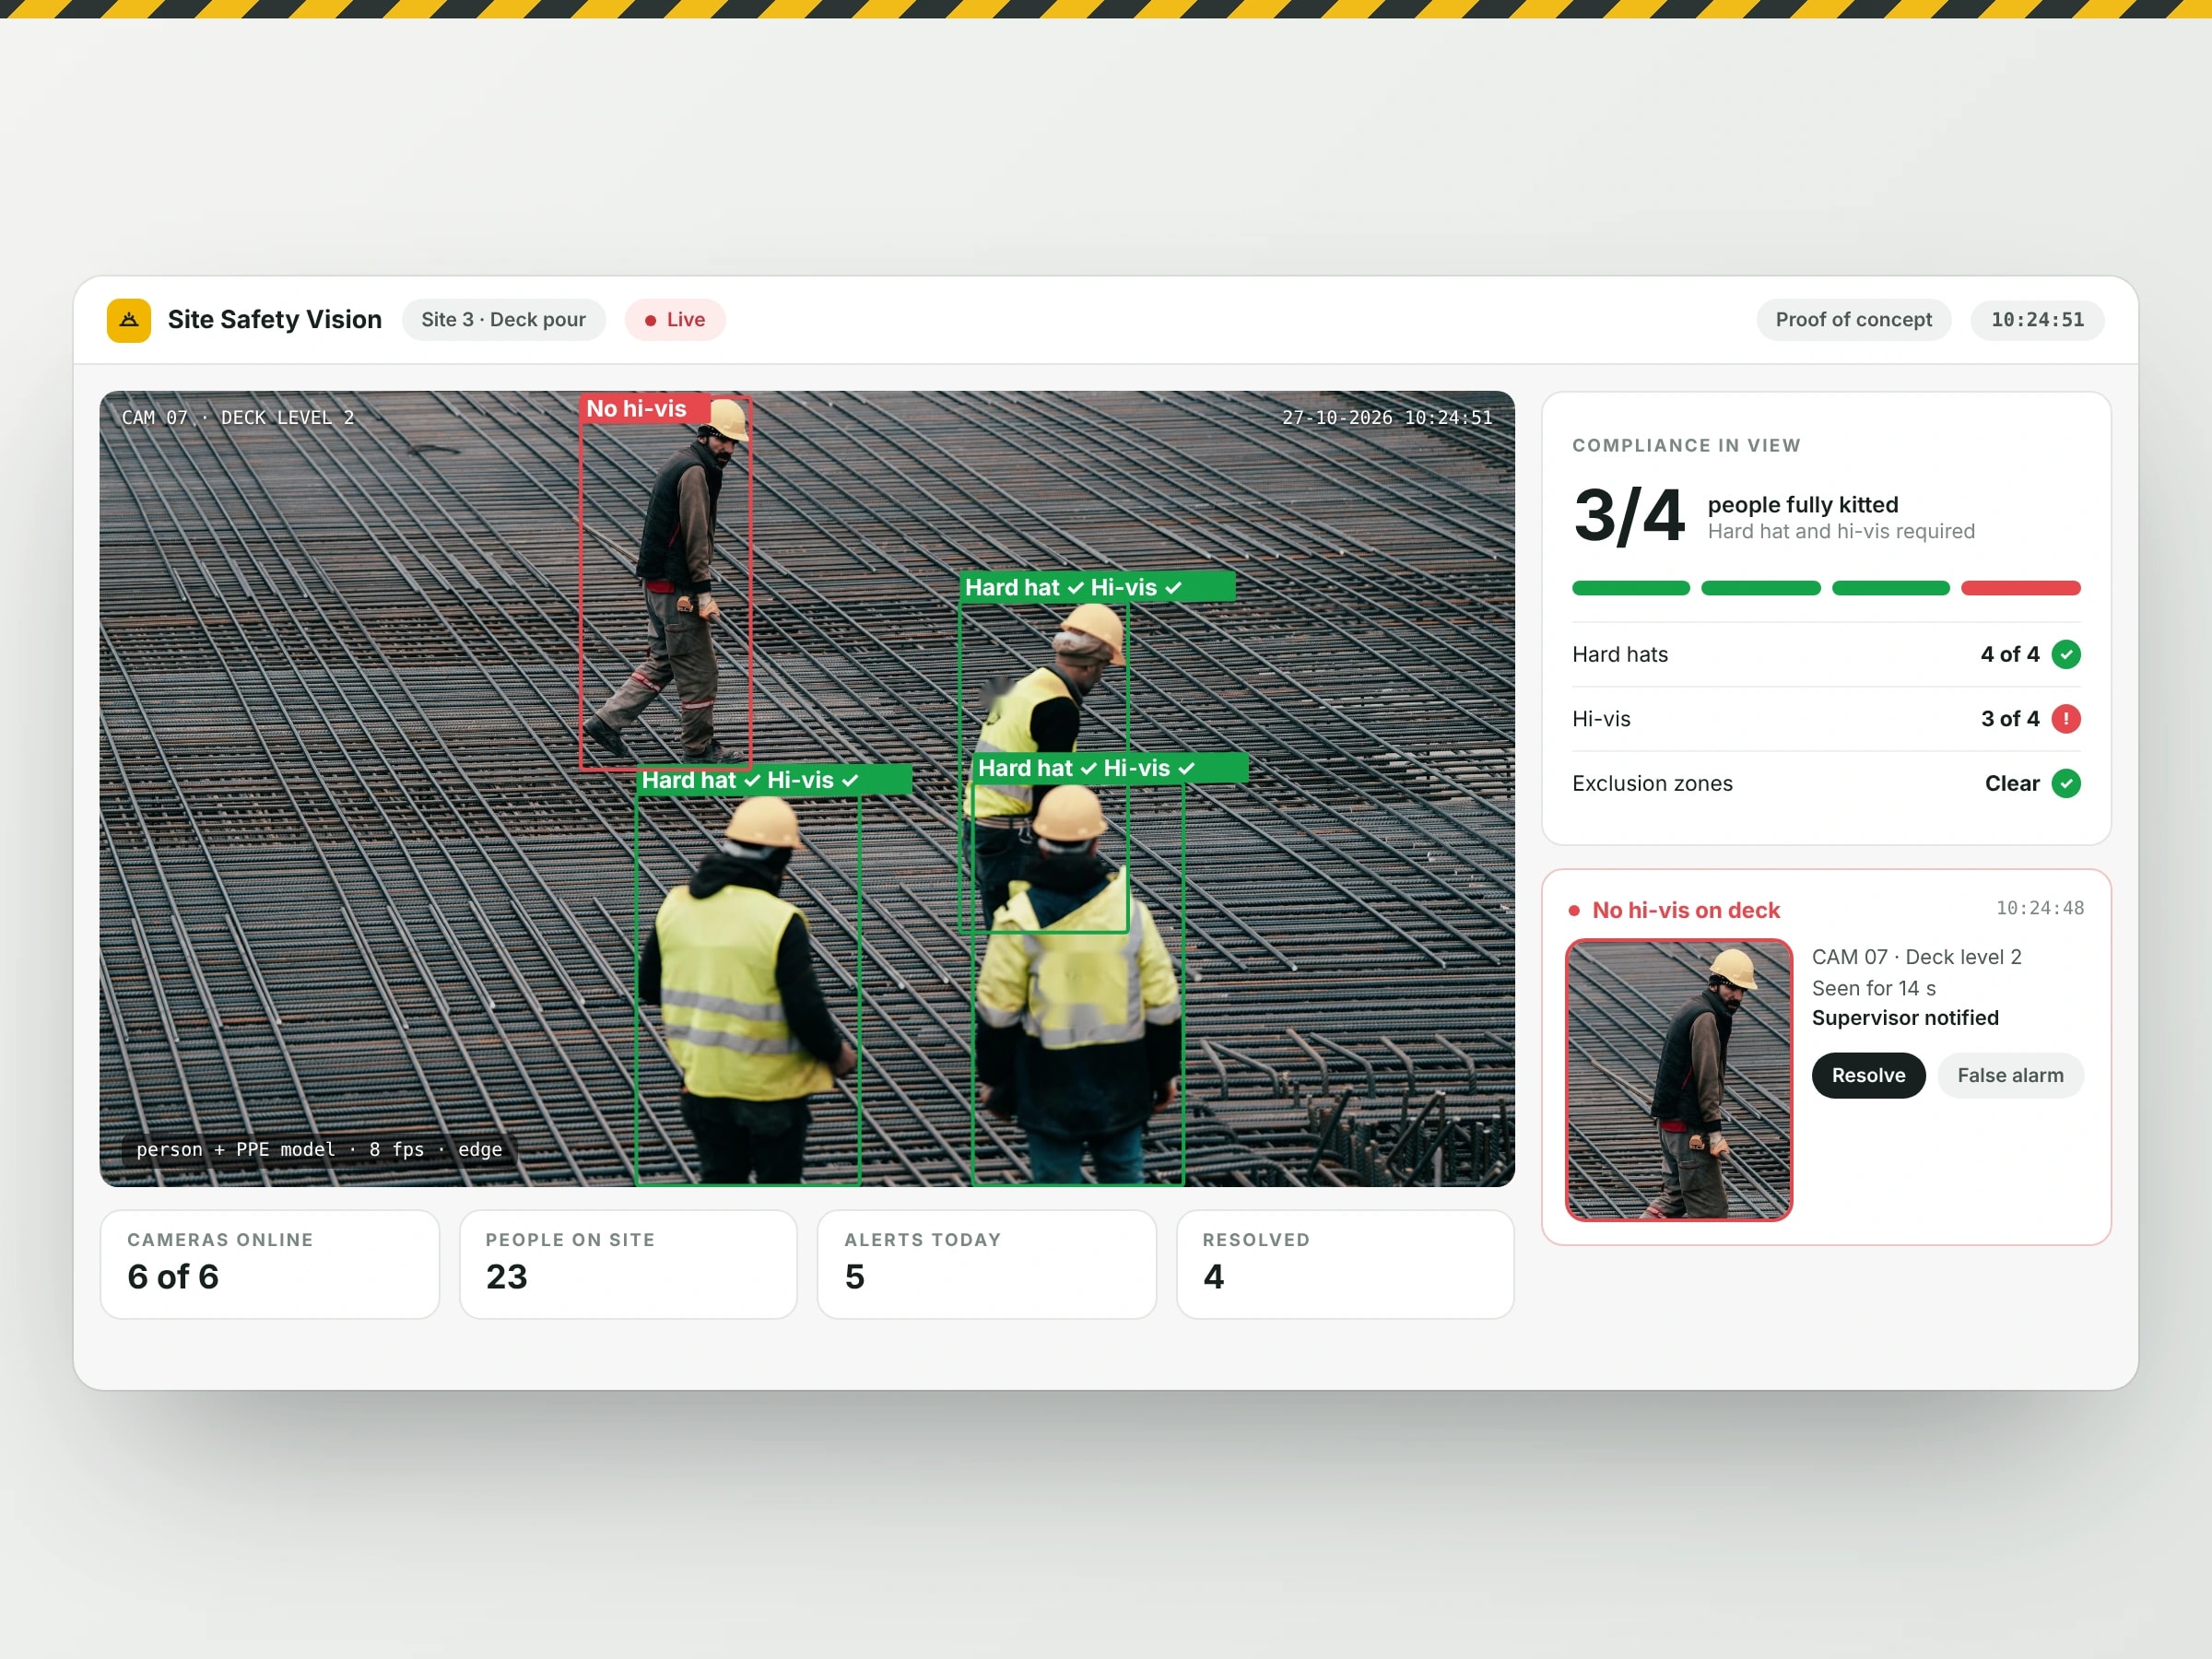
We wanted a practical way to review PPE and safety-zone events using our existing cameras. The team focused on the situations our site managers need to investigate and made the footage easier to review.
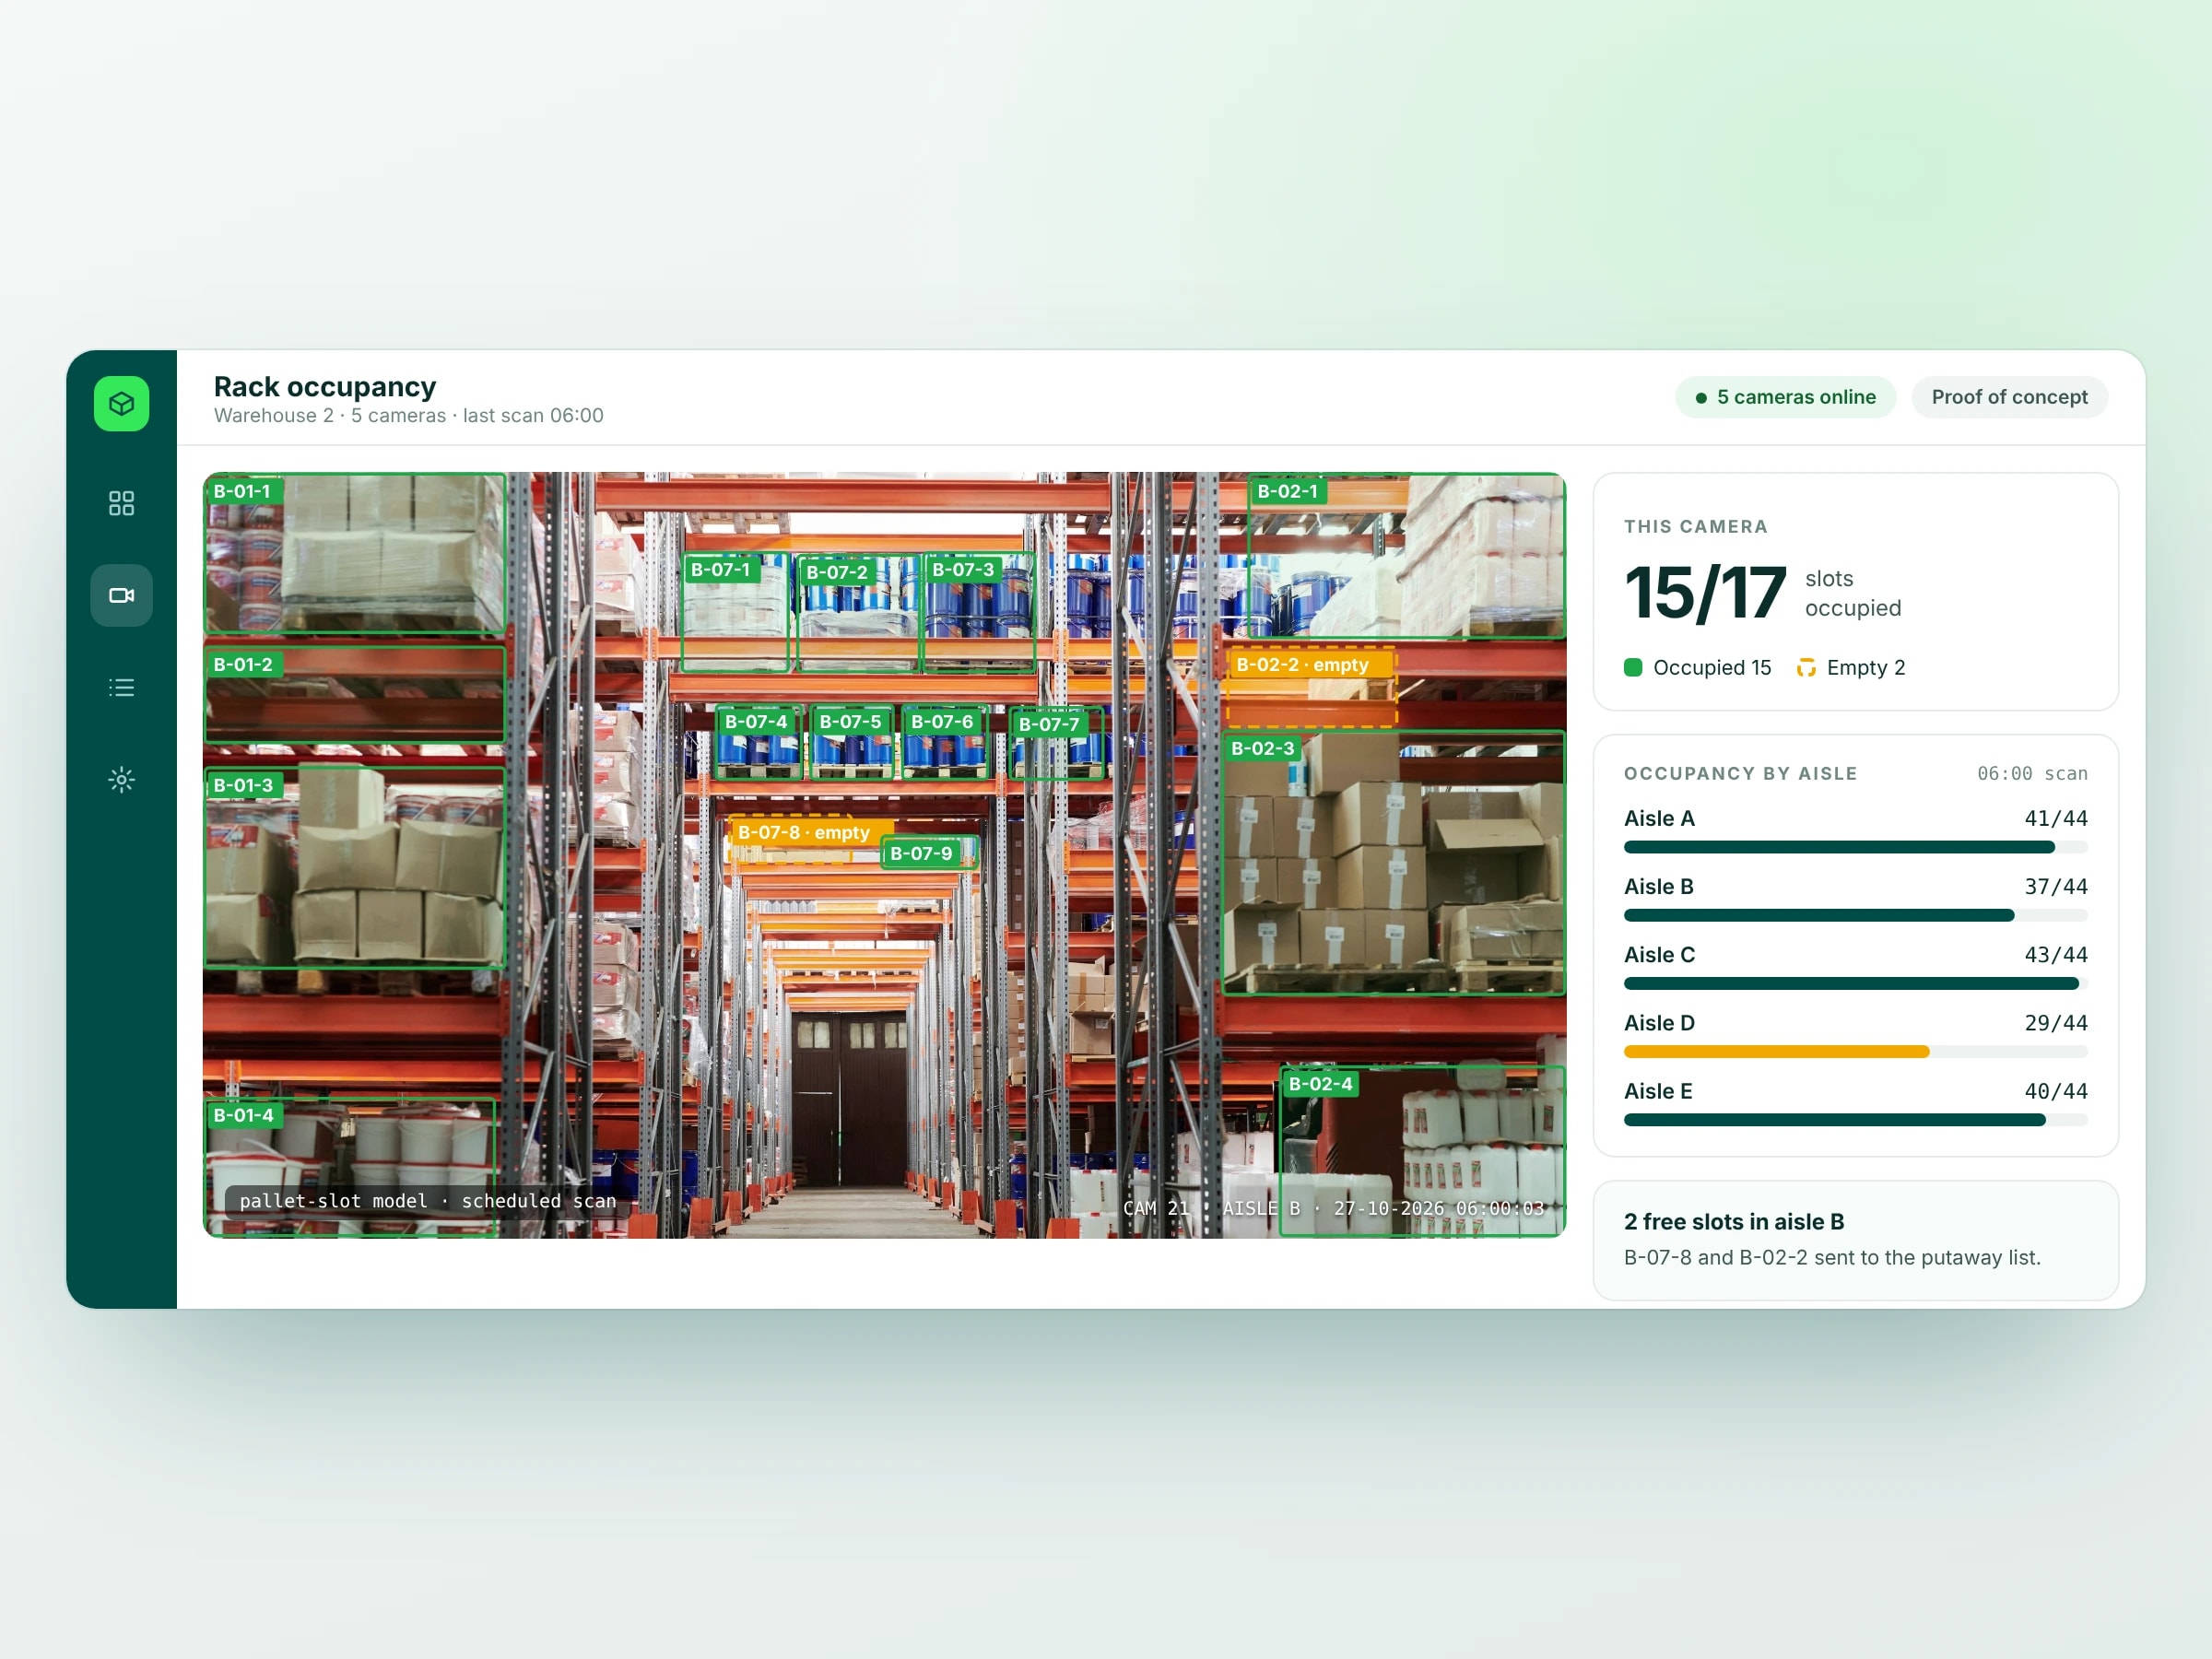
The priority was a counting workflow our warehouse team could use during a normal shift. Backendz connected image-based counts with the records we already use and made discrepancies easier to review.
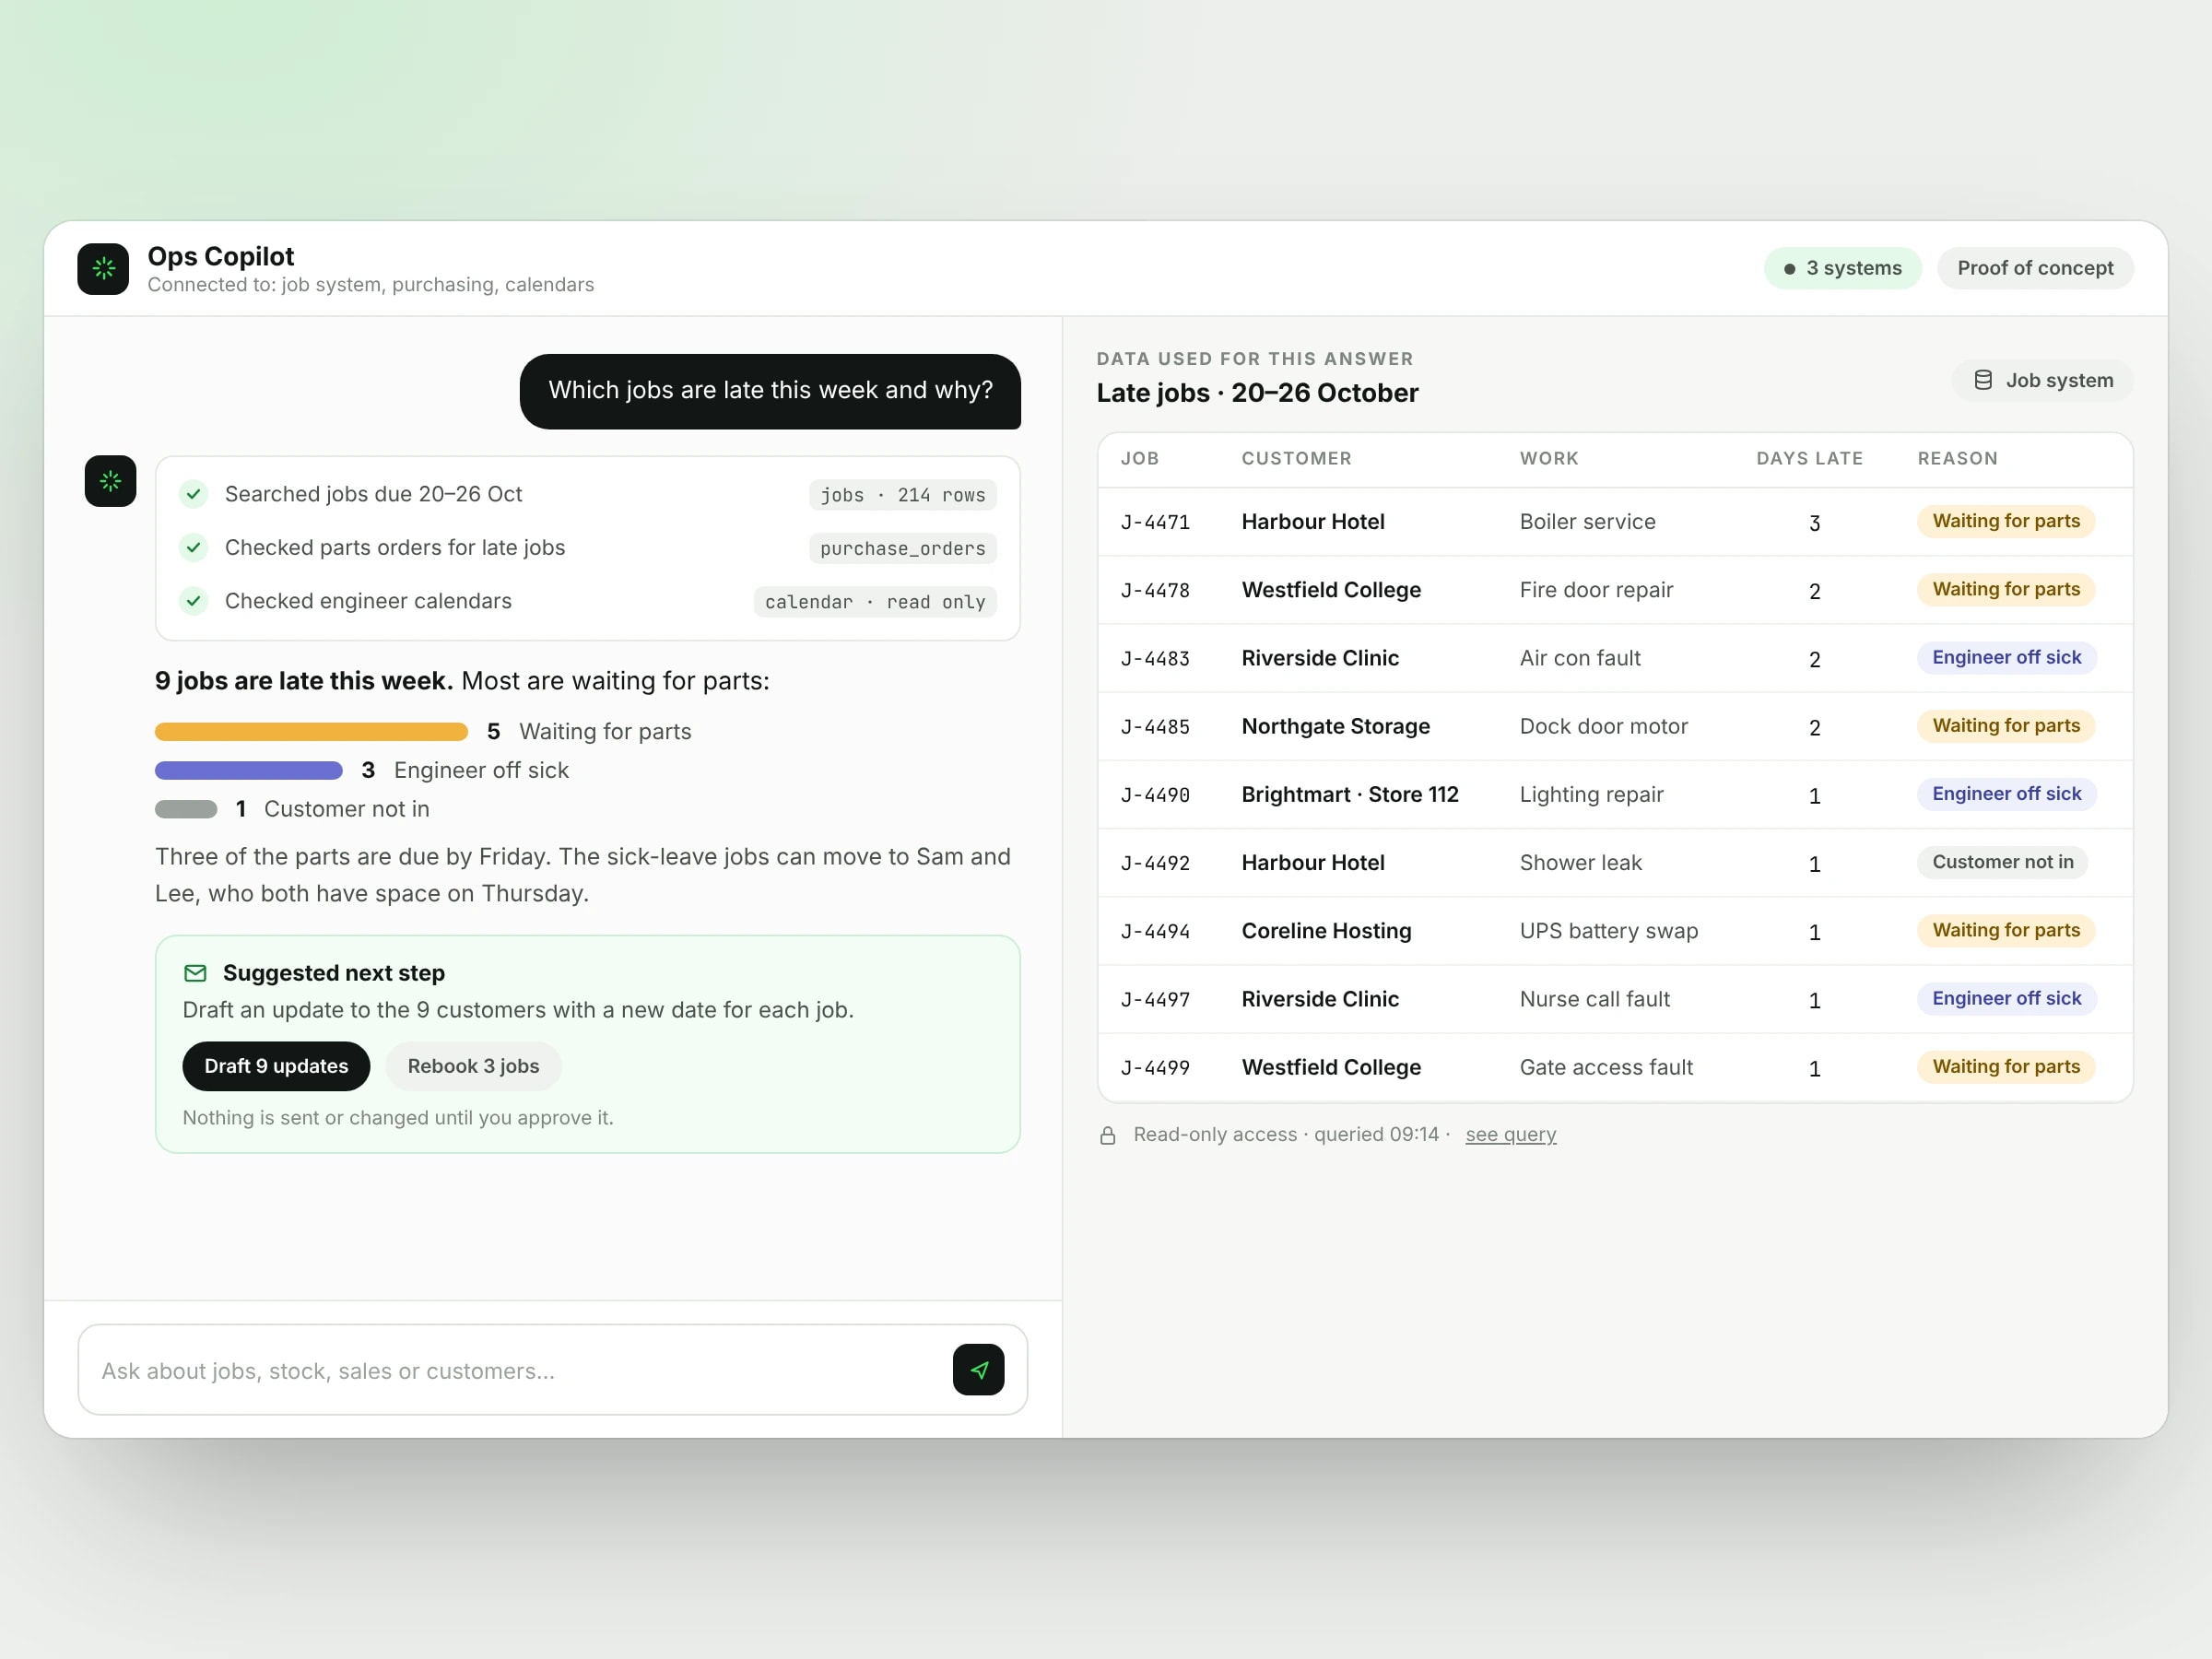
Our information was spread across several operational systems. Backendz designed a clearer way to ask questions, inspect the supporting evidence and keep approval with our team before an action is taken.
The reconciliation workflow gives our finance team one place to review mismatches and supporting records. We can trace an exception back to its source and decide what needs attention.
We had outgrown the spreadsheets that held our pricing rules. Backendz helped turn that knowledge into a quoting tool we can maintain and explain to new colleagues.
Connecting our sales and inventory systems was the priority. The integration gives our team a clearer view of updates and a practical way to investigate records that need review.
The cloud work started with understanding our existing systems and dependencies. The team documented the setup and gave us a clearer basis for monitoring and ongoing maintenance.
The engineers worked alongside our team and explained their decisions clearly. Code reviews and practical documentation helped us stay involved throughout delivery.
5 yrs
In production
We quote fixed and we hold it
2
Platforms run in-house
45
Services, one team
Senior engineers, not account managers
24/7 production support and monitoring
The things people ask before they commit.
Ask it on the call. We would rather answer an awkward question early than discover it in month three.
Book a callYes, and a good share of our support work is exactly that. We start with an audit — code, infrastructure, access, backups — and give you a written risk register before we commit to a response target, because promising a resolution time on a system we have not read would be dishonest.
A named rota, an alerting path that reaches a person, and an agreed response time by severity. We agree what counts as severity one with you up front, because that definition is where most support relationships go wrong.
Yes. Monitoring, response and an agreed allocation of maintenance time are one monthly figure. Larger pieces of work are quoted separately so you are never surprised by a support invoice.
Yes, and we write the documentation on that assumption. Runbooks, architecture notes and access stay current and stay yours, so a handover is a session rather than a project.
A written review: what happened, why, what we did, and the change that prevents it recurring — tracked to completion like any other work. If the same thing happens twice, the first review was not good enough.
Your accounts, always. We operate what you own. It keeps your billing, your data residency and your exit path entirely in your hands.